Imagine opening three reports on Monday morning.
Your marketing dashboard says revenue was $485,000.
The finance report says $462,000.
The executive dashboard says $497,000.
All three supposedly describe the same business.
Which number is correct?
This situation is more common than it may seem. Organizations invest heavily in dashboards, business intelligence platforms, cloud databases, and analytics tools, yet teams can still spend hours debating whose spreadsheet or dashboard contains the “real” number.
The problem is often blamed on the visualization.
But the chart is usually the last step in a much longer data process.
Behind every KPI is a chain of definitions, databases, transformations, joins, filters, timestamps, business rules, and assumptions. When those components are inconsistent, even a beautifully designed dashboard can communicate the wrong answer with remarkable confidence.
Good business intelligence therefore begins long before the visualization.
It begins with trustworthy data.
The Dashboard Is Only the Last Layer
A dashboard might look simple: revenue, customers, conversion rate, average order value, and several charts showing trends.
But those numbers may have traveled through multiple systems before reaching the screen.
A typical analytical workflow might look something like:
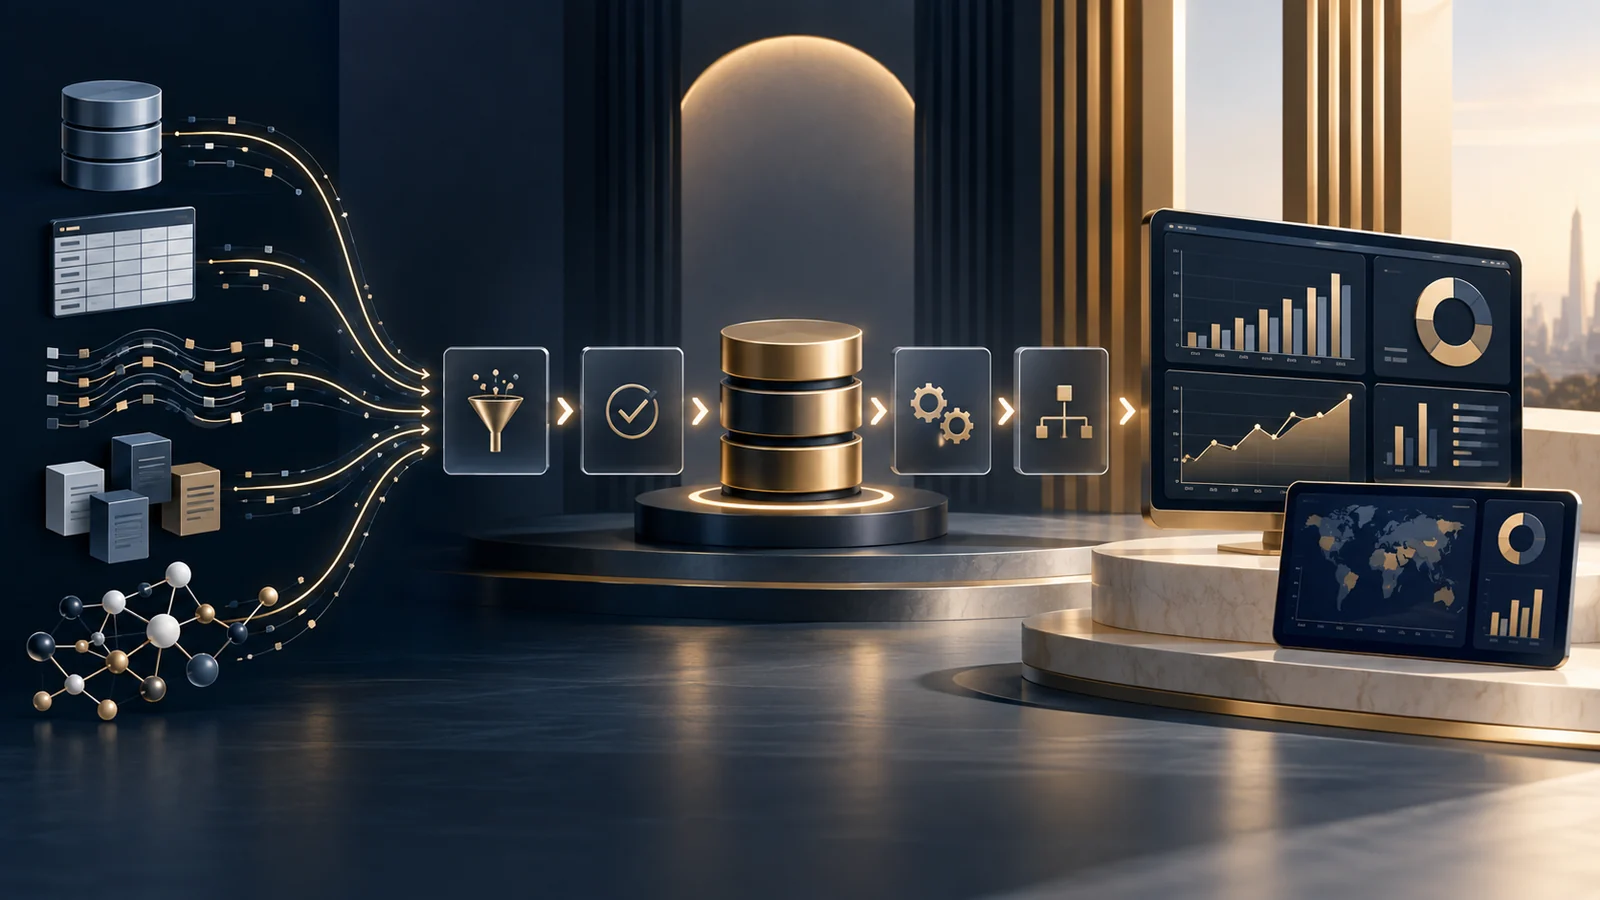
Source Systems → Data Collection → Database/Warehouse → Transformation → Business Logic → Analytical Dataset → Dashboard
Problems introduced anywhere in this chain can eventually appear as discrepancies in reporting.
For example, an ecommerce organization might combine website behavior from GA4, advertising costs from marketing platforms, transactions from an ecommerce system, customer information from a CRM, and financial records from accounting software.
Each system was designed for a different purpose.
Expecting all of them to produce identical metrics automatically is unrealistic.
The analytical challenge is creating a consistent layer between those systems and the decisions they support.
Sometimes the Data Is Correct but the Definition Is Different
Not every disagreement is actually a data-quality error.
Sometimes two dashboards calculate different versions of the same concept.
Consider something as apparently simple as revenue.
Does revenue mean:
- revenue when an order is placed?
- revenue when payment is captured?
- revenue after cancellations?
- revenue after refunds?
- revenue before tax?
- revenue after discounts?
- recognized accounting revenue?
Each definition could be valid in a particular business context.
Marketing may care about revenue attributed to campaigns. Operations may care about completed orders. Finance may follow accounting recognition rules.
The problem begins when all three metrics are simply labeled Revenue.
Before building dashboards, organizations need agreed definitions for their most important KPIs.
A metric without a clear definition is not yet a reliable business metric.
Different Data Sources See Different Versions of Reality
Analytics systems observe businesses through different lenses.
GA4, for example, primarily observes digital interactions captured through its measurement implementation.
A CRM may organize information around leads, accounts, and customers.
An advertising platform sees interactions occurring within its own advertising ecosystem.
A transactional database records operational events such as orders and payments.
An accounting system follows financial rules.
These systems should not necessarily produce identical numbers.
Suppose an advertising platform reports 500 conversions while an analytics platform reports 430.
That difference does not automatically mean one platform is broken.
The systems may use different attribution windows, identity resolution methods, event definitions, time zones, consent signals, or modeling approaches.
The first analytical task should therefore be understanding why the numbers differ rather than immediately trying to force them to match.
Joins Can Quietly Change Your Numbers
One of the most dangerous data problems happens during database joins.
Suppose an orders table contains one row per order.
A second table contains multiple products associated with each order.
Joining the tables without considering their different levels of granularity can duplicate order-level information.
An order worth $100 containing four products might suddenly appear four times.
If revenue is then summed, the analysis could report $400.
The SQL query may execute perfectly.
The dashboard may render perfectly.
The number may still be wrong.
This is why understanding the grain of a dataset—the level represented by each row—is fundamental to reliable analytics.
Before joining tables, analysts should know whether each row represents a customer, transaction, product, session, event, hospital encounter, campaign, or another unit of analysis.
Technical correctness is not the same as analytical correctness.
Missing Data Can Be More Important Than Bad Data
Organizations often search for incorrect values while overlooking missing observations.
Imagine analyzing customer acquisition costs.
Advertising spend is available for Google Ads and Meta, but one smaller advertising source failed to load into the warehouse for several weeks.
Nothing necessarily looks broken.
The dashboard still displays numbers.
The SQL still runs.
Charts still appear.
But total acquisition spending is understated, making performance appear better than it actually was.
This type of problem is particularly dangerous because the output can look completely reasonable.
Useful validation therefore asks not only:
“Are these values valid?”
but also:
“Is everything that should be here actually here?”
Completeness is a dimension of data quality.
Time Is Another Source of Disagreement
Dates are deceptively complicated.
A transaction may have:
- event timestamp
- processing timestamp
- database insertion timestamp
- local business date
- UTC timestamp
- settlement date
Two systems grouping transactions by different timestamps can produce different daily totals even when both contain the same underlying transactions.
Time-zone differences can create similar problems.
A transaction at 11:30 PM in Chicago may belong to the following calendar day in a UTC-based system.
At monthly scale this may appear minor. At daily or hourly reporting levels, it can materially affect comparisons.
Organizations therefore need consistent rules about which timestamp drives each metric.
Data Cleaning Is Really Business Logic
The phrase data cleaning sometimes sounds like a purely technical exercise: remove duplicates, fix missing values, standardize text, and continue.
In practice, many cleaning decisions require business judgment.
Consider a customer table containing duplicate email addresses.
Should the records be merged?
Perhaps.
But what if multiple people share a business email?
Or consider an unusually large transaction.
Is it an error that should be removed?
Or is it a legitimate enterprise customer?
Analytics cannot always determine these answers from the numbers alone.
Reliable data preparation combines technical methods with domain understanding.
That is one reason effective analytics work requires asking business questions before automatically applying transformations.
Build Validation Into the Pipeline
Data validation should not happen only after someone notices a strange dashboard.
It can be incorporated directly into analytical workflows.
Useful checks might include:
- row-count comparisons
- duplicate detection
- missing-value monitoring
- accepted-value ranges
- reconciliation against source totals
- referential-integrity checks
- unexpected category detection
- timestamp validation
- historical trend comparisons
Suppose yesterday's transaction table contained 85,000 records and today's pipeline produces only 7,000.
A validation rule can flag the discrepancy before the dashboard reaches executives.
The objective is not to guarantee perfect data.
It is to make failures visible earlier.
A Semantic Layer Can Reduce KPI Confusion
As organizations grow, different analysts and departments may independently recreate the same metrics.
One team calculates customer acquisition cost in SQL.
Another builds the calculation in Tableau.
A third calculates it inside a spreadsheet.
Eventually, the organization has three versions of CAC.
A shared semantic or metric layer can reduce this problem by centralizing important business definitions.
Instead of every dashboard redefining revenue, active customers, conversion rate, or retention, those definitions can be standardized and reused.
The technical implementation varies across analytics stacks.
The underlying principle is more important:
A KPI should have an owner, a definition, and a repeatable calculation.
Data Lineage Helps Answer “Where Did This Number Come From?”
When someone questions a dashboard metric, analysts should ideally be able to trace it backward.
Where did the data originate?
Which transformations were applied?
Which records were excluded?
Which business rule calculated the metric?
Which version of the source table was used?
This concept is known as data lineage.
Lineage becomes increasingly important as analytical environments grow more complex.
Without it, debugging becomes detective work.
With it, organizations can trace a suspicious number through the analytical pipeline and identify where the discrepancy originated.
Better Dashboards Start With Better Questions
It is tempting to begin an analytics project by discussing charts.
Should we use a bar chart?
Should the dashboard have filters?
Should executives see a map?
Those questions matter eventually.
But more important questions come first.
What decision will this metric support?
What exactly does the metric mean?
Which system should be considered authoritative?
At what level should the data be analyzed?
How frequently should it update?
What transformations are required?
How will we know whether the output is correct?
Once those questions have clear answers, visualization becomes much easier.
Trust Is an Analytics Asset
A dashboard loses value quickly when users stop trusting it.
If managers repeatedly discover unexplained discrepancies, they begin exporting data into spreadsheets, creating parallel calculations, and maintaining their own versions of important metrics.
That creates even more inconsistency.
Reliable analytics therefore has a compounding effect.
Consistent definitions increase trust.
Trust increases adoption.
Adoption creates better feedback.
Better feedback improves the analytical system.
The opposite cycle is also possible.
Poor data quality creates conflicting numbers, conflicting numbers reduce trust, and reduced trust encourages fragmented reporting.
The Goal Is Not One Perfect Database
Businesses rarely operate from one perfectly organized source.
Modern organizations use many specialized systems, and those systems will continue to contain different representations of the business.
The objective is not necessarily to eliminate every discrepancy.
It is to understand them, define authoritative metrics, establish appropriate transformations, validate critical data, and create a reliable analytical layer for decision-making.
The next time two dashboards disagree, the most useful question may therefore not be:
“Which dashboard is wrong?”
Instead ask:
“What happened to the data before it reached the dashboard?”
That question often leads much closer to the real problem.
Build Analytics People Can Trust
UAD Consulting helps organizations turn fragmented business data into structured analysis, reliable KPIs, and decision-focused reporting through business analytics, data engineering, database analytics, and visualization.
Explore ServicesGet in Touch